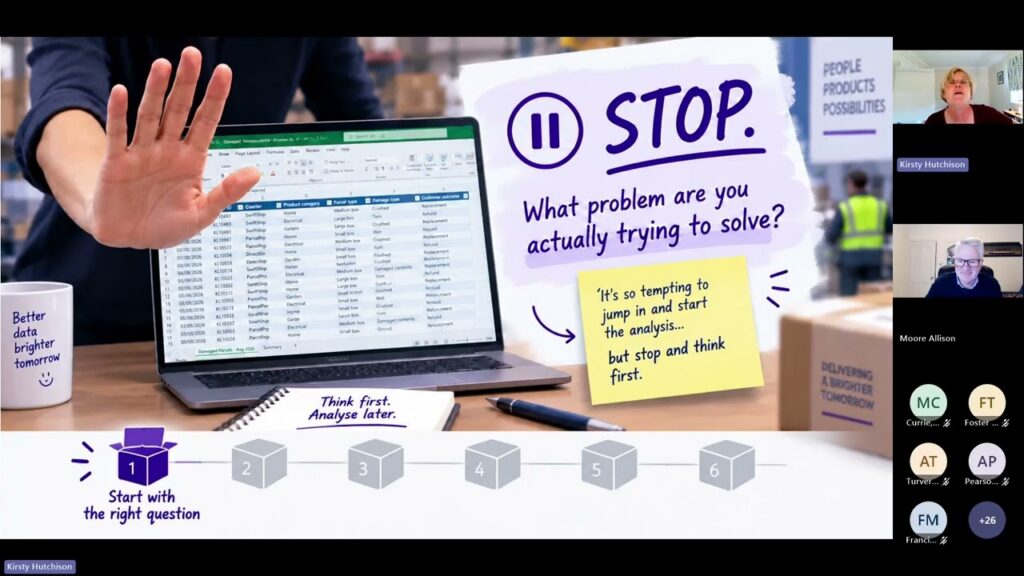
An operations manager sends an improvement team a spreadsheet of damaged parcels. A new courier has recently been appointed, and the manager wants the data to confirm whether the courier is responsible. The request sounds reasonable. The spreadsheet is ready. The temptation is to start drawing charts.
But the proposed cause has arrived before the problem has been properly defined. In her Back to Better webinar, Catalyst Master Black Belt Kirsty Hutchison uses this example to show why the first step in a data project is to ask a better question, not to select an analysis tool. Her six insights offer a practical way to keep the work focused on the problem that matters.
Start with the problem, not the suspected cause
“Is the new courier causing damage?” is a hypothesis. It is not a problem statement. Before comparing couriers, the team needs to establish whether damage has actually increased, by how much, over what period and across which deliveries. It needs to understand the effect on customers and the business.
This pause matters because a sponsor’s explanation can shape the entire investigation. If the team accepts the courier as the problem, it may gather only courier data and miss a change elsewhere in the process. Sometimes a closer look reveals that the apparent increase was a short-lived spike, or that there was no meaningful change at all.
Plan the analysis backwards
Once the problem is clear, Kirsty recommends sketching the outputs you want before collecting more data. What should the final charts show? Do you need the proportion of damaged deliveries by week, the cost of refunds, or a comparison across product types? What decision will each view help the team make?
Work backwards from those questions to the data format and collection plan. To plot a damage rate over time, for example, you need both the number of damaged parcels and the total number delivered in each period. A list containing only complaints cannot provide the denominator. Dates, definitions and the amount of data collected must also support the analysis you intend to perform.
This approach can save a familiar frustration: receiving a large spreadsheet, drawing a chart, and then discovering that it cannot answer the question the project actually needs to resolve.
Know whether the data can be trusted
Available data is a useful starting point, but it may have been collected for a different purpose. Before treating it as evidence, ask where it came from, who recorded it and whether the process was consistent. The people doing the work can often explain gaps or changes that are invisible in the spreadsheet.
Even a simple label such as “damaged” needs a shared definition. Does a scuffed outer box count? What about a puncture or broken contents? If different teams classify the same parcel differently, a comparison between weeks or couriers can mislead. Clear operational definitions and, where useful, visual standards make the measurement more repeatable.
Look at the outcome over time before chasing causes
With reliable data in hand, the next temptation is to split it by courier, parcel weight or packaging type. Kirsty suggests starting with the outcome you want to improve: in this example, the proportion of damaged deliveries. Plot it in time order first, using a run chart or a suitable control chart.
In the webinar’s illustrative case, that view reveals a shift at the point when new packaging material was introduced. The new courier had seemed an obvious suspect, but the time sequence opens a different line of enquiry. It does not by itself prove that packaging caused the damage; it tells the team where to investigate next.
Let the question evolve
A good analysis plan gives the work direction, but it cannot predict every finding. The packaging clue creates a fresh question and may require data that was not in the original spreadsheet. Rather than forcing the initial plan to completion, the team needs to collect evidence that can test the new possibility.
That need not mean months of work or a vast data set. Kirsty describes how a small, carefully designed experiment could compare packaging performance. Relevant data gathered under known conditions may be more useful than a large volume of historic records whose quality or meaning is uncertain. The test still needs enough observations and appropriate controls to support the conclusion.
Stay curious when the evidence challenges the brief
The final discipline is resisting the pressure to “prove” a preferred cause. In Kirsty’s example, a comparison of damage rates across couriers does not support blaming the new supplier. That is a useful result: ruling out a plausible explanation can prevent a costly response to the wrong problem.
Sponsors can help by staying involved from the start, agreeing what the team is trying to learn and reviewing findings as the question develops. When the evidence changes direction, the discussion is then about solving the underlying problem, rather than defending an early assumption.
The lesson is simple to state and easy to forget when an urgent spreadsheet lands in your inbox: define the effect, plan the evidence you need, check the measurement, understand what has changed over time, and remain willing to follow what you find. Better analysis starts before the first chart.
Watch the full webinar
Watch Kirsty Hutchison explore these six insights in Insight Before Analysis: Why Most Data Projects Solve the Wrong Problem.